
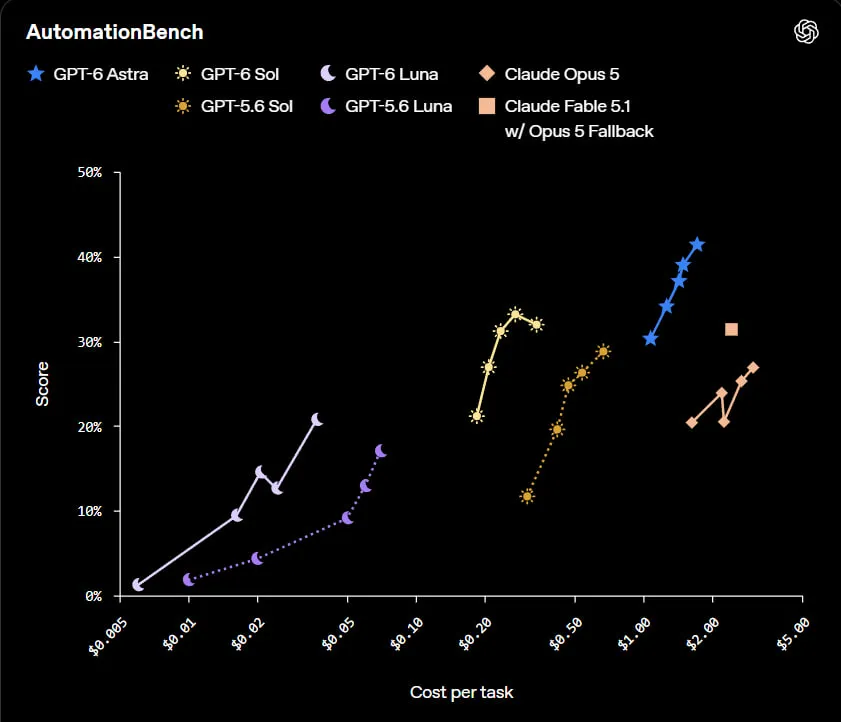
In the AutomationBench workload tests, Sol outperforms Claude Opus 5 (33.2% vs. 26.9%) and Fable 5.1 (31.4%)—while task execution costs roughly 11 times less than Opus 5.
In an internal test of real-world errors, Sol saw its error rate cut in half compared to GPT-5.6. Sol’s reliability is approaching that of Astra at a lower price. Basic API pricing for Sol has been reduced by 50% ($2/$10 per million tokens), and for Luna, by 50-58%.
Sol is designed for complex coding and agent-based tasks (feature development, code review, debugging, data analysis); Luna is suited for simpler, more mass-market tasks such as summarization and data extraction.
Continue reading this article on source: openai.com