
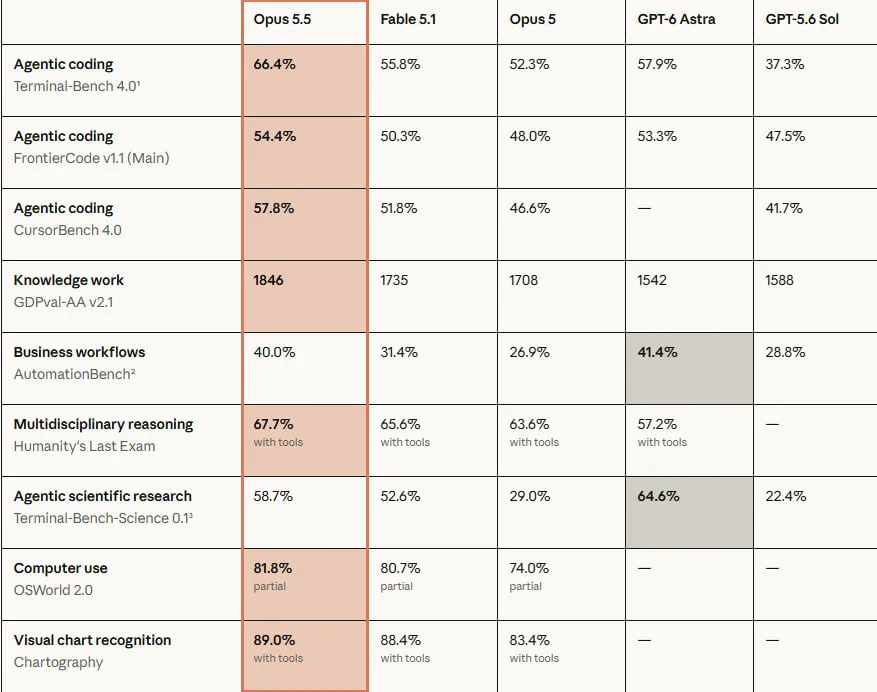
In terms of performance, it does not lag behind Claude Fable 5.1 in most tasks and is 40% cheaper to operate than Opus 5.
In benchmarks, the model outperforms GPT-5.6 Sol in 6 out of 6 general tests in the release, and GPT-6 Astra in 4 out of 6 (independent tests confirm at least Terminal-Bench 4.0: 66.4% versus 57.9% for Astra)
Users note a significant increase in speed on real-world tasks—for example, auditing a codebase of 200,000 lines took less than 3 hours, compared to over 20 hours for the previous version.
Continue reading this article on source: anthropic.com